Which AI builds best?
Eight models get the same brief and 150 rectangles. One shot each, scored from 0 to 100 against the exact target. A new round every week.
Week 2026-W47, Nov 16 to 19
This week
Week 2026-W47, Nov 16 to 19
Change compared with last week.
What each model built
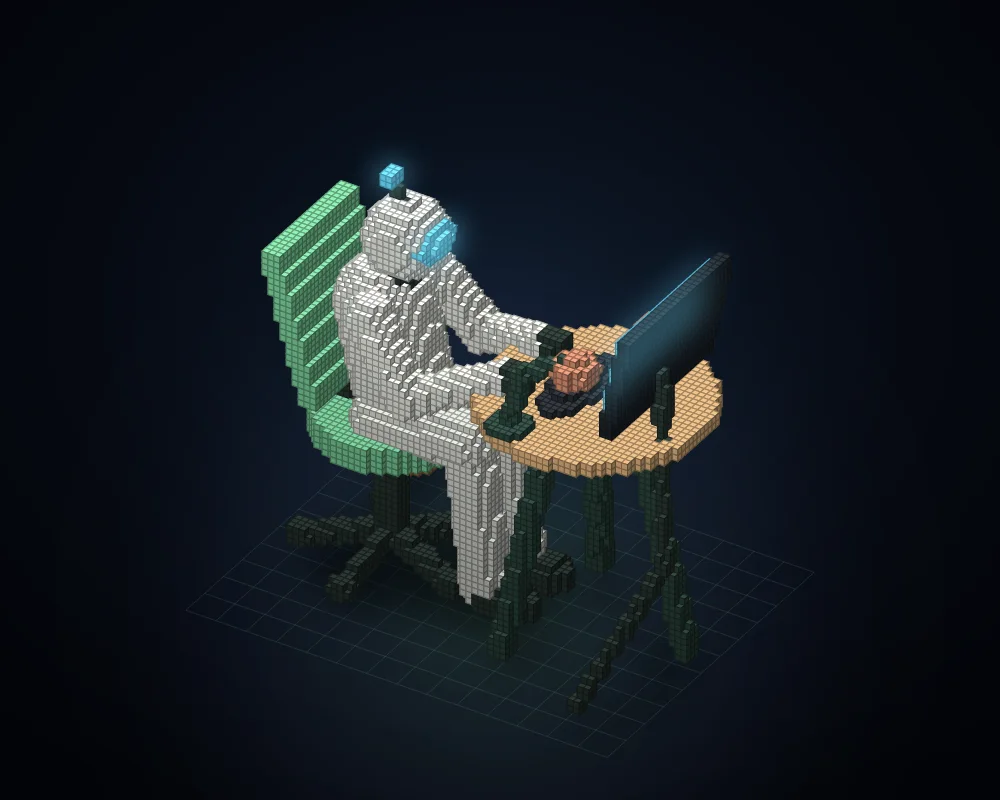
Raw output, rendered from the JSON each model returned. The dashed outline is the target.


Notes
Is it nerfed?
Same brief every week, so a model that suddenly scores lower is worth a look. We compare each round with the model’s own average of the four rounds before.
What did each result take?
Input plus output tokens, and elapsed time, for the same week. Models on the dashed line are not beaten on both score and cost by any other.
Week 2026-W47
View token and runtime measurements
Why do input tokens differ? Every model receives the same benchmark brief, but these are provider-reported counts for the full CLI run, including built-in instructions. Models can tokenize the same text differently, and continuation requests can count context again. Claude input totals include uncached tokens plus cache reads and writes. Reasoning tokens are counted only as the provider reports them. Missing values are left blank. The reported counts do not measure prices.
Round over round
The starting round keeps its original results. Every point after it is a fresh round, measured that week.
View the recorded scores
Starting baseline preserves the original first-round results and measurement dates.
| Round | Claude Opus 5 / Claude Opus 5.5 | Claude Sonnet 5 / Claude Sonnet 5.5 | Claude Fable 5.1 / Claude Fable 5.2 | GPT-6.1 Sol / GPT-6.2 Sol | GPT-6 Astra / GPT-6.2 Astra | GPT-6 Luna | GPT-6.1 Terra | Claude Haiku 5.5 |
|---|---|---|---|---|---|---|---|---|
| 2026-W47 | 74.7 (Claude Opus 5.5) | 60.8 (Claude Sonnet 5.5) | 79.3 (Claude Fable 5.2) | 84.6 (GPT-6.2 Sol) | 78.5 (GPT-6.2 Astra) | 34.9 (GPT-6 Luna) | 70.7 (GPT-6.1 Terra) | 72.6 (Claude Haiku 5.5) |
| 2026-W46 | 74.8 (Claude Opus 5.5) | 61 (Claude Sonnet 5.5) | 79.3 (Claude Fable 5.2) | 72.5 (GPT-6.1 Sol) | 79.1 (GPT-6 Astra) | 38.8 (GPT-6 Luna) | 70.3 (GPT-6.1 Terra) | 65.3 (Claude Haiku 5.5) |
| 2026-W45 | 80.1 (Claude Opus 5.5) | 56.7 (Claude Sonnet 5.5) | 77.8 (Claude Fable 5.1) | 76.4 (GPT-6.1 Sol) | 78 (GPT-6 Astra) | 41.8 (GPT-6 Luna) | 71.3 (GPT-6.1 Terra) | 66 (Claude Haiku 5.5) |
| 2026-W44 | 74.4 (Claude Opus 5.5) | 64.9 (Claude Sonnet 5.5) | 76.9 (Claude Fable 5.1) | 81.4 (GPT-6.1 Sol) | 77.7 (GPT-6 Astra) | 46.7 (GPT-6 Luna) | 73.1 (GPT-6.1 Terra) | 73.2 (Claude Haiku 5.5) |
| 2026-W43 | 75.9 (Claude Opus 5.5) | 61 (Claude Sonnet 5.5) | 75.7 (Claude Fable 5.1) | 72.5 (GPT-6.1 Sol) | 79.7 (GPT-6 Astra) | 33.9 (GPT-6 Luna) | - | 73.6 (Claude Haiku 5.5) |
| 2026-W42 | 75.1 (Claude Opus 5.5) | 67.4 (Claude Sonnet 5.5) | 69 (Claude Fable 5.1) | 77.9 (GPT-6.1 Sol) | 78.4 (GPT-6 Astra) | 43.7 (GPT-6 Luna) | - | 65.7 (Claude Haiku 5.5) |
| 2026-W41 | 78.5 (Claude Opus 5.5) | 48.1 (Claude Sonnet 5.5) | 74.6 (Claude Fable 5.1) | 74.7 (GPT-6.1 Sol) | 73.5 (GPT-6 Astra) | 30.9 (GPT-6 Luna) | - | 68.4 (Claude Haiku 5.5) |
| Starting baseline | 75.5 (Claude Opus 5) | 34.3 (Claude Sonnet 5) | 71.2 (Claude Fable 5.1) | 70.6 (GPT-6.1 Sol) | 77.5 (GPT-6 Astra) | 45.6 (GPT-6 Luna) | - | - |
Every weekly run
Generated from the same records as the chart. Each week has its own address, for example https://vibeide.dev/benchmark/#2026-w47. Download every run as CSV.
| Week | Run date | Model | Score | Change vs previous round |
|---|---|---|---|---|
| 2026-W47 | GPT-6.2 Sol | 84.6 | New model version | |
| 2026-W47 | Claude Fable 5.2 | 79.3 | 0.0 | |
| 2026-W47 | GPT-6.2 Astra | 78.5 | New model version | |
| 2026-W47 | Claude Opus 5.5 | 74.7 | -0.1 | |
| 2026-W47 | Claude Haiku 5.5 | 72.6 | +7.3 | |
| 2026-W47 | GPT-6.1 Terra | 70.7 | +0.4 | |
| 2026-W47 | Claude Sonnet 5.5 | 60.8 | -0.2 | |
| 2026-W47 | GPT-6 Luna | 34.9 | -3.9 | |
| 2026-W46 | Claude Fable 5.2 | 79.3 | New model version | |
| 2026-W46 | GPT-6 Astra | 79.1 | +1.1 | |
| 2026-W46 | Claude Opus 5.5 | 74.8 | -5.3 | |
| 2026-W46 | GPT-6.1 Sol | 72.5 | -3.9 | |
| 2026-W46 | GPT-6.1 Terra | 70.3 | -1.0 | |
| 2026-W46 | Claude Haiku 5.5 | 65.3 | -0.7 | |
| 2026-W46 | Claude Sonnet 5.5 | 61 | +4.3 | |
| 2026-W46 | GPT-6 Luna | 38.8 | -3.0 | |
| 2026-W45 | Claude Opus 5.5 | 80.1 | +5.7 | |
| 2026-W45 | GPT-6 Astra | 78 | +0.3 | |
| 2026-W45 | Claude Fable 5.1 | 77.8 | +0.9 | |
| 2026-W45 | GPT-6.1 Sol | 76.4 | -5.0 | |
| 2026-W45 | GPT-6.1 Terra | 71.3 | -1.8 | |
| 2026-W45 | Claude Haiku 5.5 | 66 | -7.2 | |
| 2026-W45 | Claude Sonnet 5.5 | 56.7 | -8.2 | |
| 2026-W45 | GPT-6 Luna | 41.8 | -4.9 | |
| 2026-W44 | GPT-6.1 Sol | 81.4 | +8.9 | |
| 2026-W44 | GPT-6 Astra | 77.7 | -2.0 | |
| 2026-W44 | Claude Fable 5.1 | 76.9 | +1.2 | |
| 2026-W44 | Claude Opus 5.5 | 74.4 | -1.5 | |
| 2026-W44 | Claude Haiku 5.5 | 73.2 | -0.4 | |
| 2026-W44 | GPT-6.1 Terra | 73.1 | First run | |
| 2026-W44 | Claude Sonnet 5.5 | 64.9 | +3.9 | |
| 2026-W44 | GPT-6 Luna | 46.7 | +12.8 | |
| 2026-W43 | GPT-6 Astra | 79.7 | +1.3 | |
| 2026-W43 | Claude Opus 5.5 | 75.9 | +0.8 | |
| 2026-W43 | Claude Fable 5.1 | 75.7 | +6.7 | |
| 2026-W43 | Claude Haiku 5.5 | 73.6 | +7.9 | |
| 2026-W43 | GPT-6.1 Sol | 72.5 | -5.4 | |
| 2026-W43 | Claude Sonnet 5.5 | 61 | -6.4 | |
| 2026-W43 | GPT-6 Luna | 33.9 | -9.8 | |
| 2026-W42 | GPT-6 Astra | 78.4 | +4.9 | |
| 2026-W42 | GPT-6.1 Sol | 77.9 | +3.2 | |
| 2026-W42 | Claude Opus 5.5 | 75.1 | -3.4 | |
| 2026-W42 | Claude Fable 5.1 | 69 | -5.6 | |
| 2026-W42 | Claude Sonnet 5.5 | 67.4 | +19.3 | |
| 2026-W42 | Claude Haiku 5.5 | 65.7 | -2.7 | |
| 2026-W42 | GPT-6 Luna | 43.7 | +12.8 | |
| 2026-W41 | Claude Opus 5.5 | 78.5 | New model version | |
| 2026-W41 | GPT-6.1 Sol | 74.7 | +4.1 | |
| 2026-W41 | Claude Fable 5.1 | 74.6 | +3.4 | |
| 2026-W41 | GPT-6 Astra | 73.5 | -4.0 | |
| 2026-W41 | Claude Haiku 5.5 | 68.4 | First run | |
| 2026-W41 | Claude Sonnet 5.5 | 48.1 | New model version | |
| 2026-W41 | GPT-6 Luna | 30.9 | -14.7 | |
| 2026-W41 (Starting baseline) | GPT-6 Astra | 77.5 | First run | |
| 2026-W41 (Starting baseline) | Claude Opus 5 | 75.5 | First run | |
| 2026-W41 (Starting baseline) | Claude Fable 5.1 | 71.2 | First run | |
| 2026-W41 (Starting baseline) | GPT-6.1 Sol | 70.6 | First run | |
| 2026-W41 (Starting baseline) | GPT-6 Luna | 45.6 | First run | |
| 2026-W41 (Starting baseline) | Claude Sonnet 5 | 34.3 | First run |
How it works
One brief
The brief lists every shape of the target with exact numbers.
One shot
Each model answers once as JSON. No hints or best-of-N.
One score
Shape match and color match against the target, 0 to 100.
Full methodology, questions and citation
Last updated
The formula
volume overlap % × share of correctly colored cubesMeasured in 1 cm³ units. Brief fingerprint 08fb5a5773fe89e7. The starting baseline preserves the original first-round results.
How it works
The brief lists every shape of the target with exact numbers. Each model answers with JSON only: up to 150 boxes, each a position, a size and one of 11 colors. The model draws nothing itself. When a run is scored we render its boxes and the target from the same small cubes, with the same light and camera, and publish the pictures.
The score is the volume overlap between sculpture and target (intersection over union, measured in 1 cm cubes) times the share of shared cubes with the right color. One box per shape scores under 40; slicing every shape into equal slabs scores about 50. Slanted legs, thin cables and round heads reward models that plan where each box goes, and the Difference view shows every missing, extra and wrongly colored cube.
Fair and repeatable
The starting baseline is the original first round, preserved with its actual measurement dates. A second measured round was requested for launch. Both are shown; neither is backdated or selected as a best-of-two result. Later rounds follow the weekly schedule.
- Same brief, same scorer and same settings every week. Brief v3 has the fingerprint
08fb5a5773fe89e7; any change starts a new version and a new chart. - Each model answers once at medium reasoning effort, through Claude Code or Codex signed in with a subscription, the same way VibeiDE runs them. No tools, no web, no best-of-N.
- A reply in which no box can be scored (not JSON, or every box malformed) is a format failure, not a sculpture: the model is asked once more and that answer loses 2 points.
- Models run one after another, never in parallel. An answer that does not arrive within 40 minutes scores 0.
- The scorer is a deterministic program. No model grades another model.
Read the full brief (plain text, 7,691 characters). Model names are the aliases each CLI offers; the page records the model identifier the CLI reported.
Questions
Is Claude or GPT getting nerfed?
This page cannot see inside a provider, but it shows whether the same model name scores differently on the same frozen task over time. One run per week is a single sample, so treat a move of a few points as noise and a drop that lasts several weeks as a signal.
Why can no model reach 100?
The target is made of spheres, ellipsoids, cylinders and slanted capsules, and the answer may only use 150 axis-aligned boxes. Boxes cannot follow curves exactly, so every answer loses some volume. Better models spend their boxes where the curves are, and their sculptures look more like the target.
How are the models run?
Each model gets the brief once through its official command-line tool, Claude Code or Codex, signed in with a normal subscription, at medium reasoning effort. Tools, sub-agents and web access are off; a run that still uses a tool loses a quarter of its score. Only a reply in which no box can be scored is asked once more, and that answer loses 2 points. The reply is scored by a deterministic program, not by another model.
Why did the benchmark change to v3?
The first two versions asked models to lay out an office. In their first rounds the best models scored 100 and 92, and every correct office looked the same. A benchmark that top models max out cannot show change, and one where answers look alike cannot show quality, so v3 asks for a sculpture whose quality is visible at a glance.
Can I try the brief myself?
Yes. The complete brief is public as plain text. Paste it into any model and compare its answer with the target.
Cite this benchmark
- Title
- VibeiDE Robot scene v1: weekly Claude and GPT model tracking
- URL
https://vibeide.dev/benchmark/- Latest week
- 2026-W47, run
- Publisher
- Crowie s.r.o.
- Method
- Each model answers the same frozen brief once at medium reasoning effort, with no tools. A reply with no usable boxes is asked once more, with a 2-point penalty. Volume overlap against the target, weighted by color accuracy, from 0 to 100.
- Licence
- Benchmark data and charts are licensed under CC BY 4.0. Please credit 'VibeiDE benchmark' with a link to https://vibeide.dev/benchmark/.
Suggested citationCrowie s.r.o. (2026). VibeiDE Robot scene v1: weekly Claude and GPT model tracking, week 2026-W47. https://vibeide.dev/benchmark/#2026-w47